 Loop Forge
Projects
Every Loop Forge project has a page here with its findings, every prompt it used, the reference images, settings, links and the YouTube video that goes with it. 11 so far, newest first.
4 November 2026
NewMOSS-Image add-ons, tested locally
MOSS-Image is OpenMOSS's open image model, released in October under Apache 2.0. Most of the interest is in its text: it spells long lines and follows a layout prompt that says where everything goes. I ran it in ComfyUI on my RTX 3060 with the official templates, then tried the add-ons people are downloading: layout boxes, chinoll's edit LoRA, two Anime2Real LoRAs, CharRef, depth control, three comic page LoRAs, two transparency LoRAs, the DMD 8-step LoRA, Spectrum, a hi-res LoHa and Scale ROPE and three smaller text encoders.
47 prompts, MOSS-Image
Updated 28 October 2026
UpdatedMiniMax H3 camera shots
Part 2 added: fifteen more shots, and a fix for the crash zoom
MiniMax H3 documents twelve camera motions and no named shots. There is no dolly zoom button and no crash zoom button, so every named film shot has to be written as a sentence built out of those twelve. Most ways of doing that do not work. These fourteen do.
30 prompts, MiniMax H3
11 October 2026
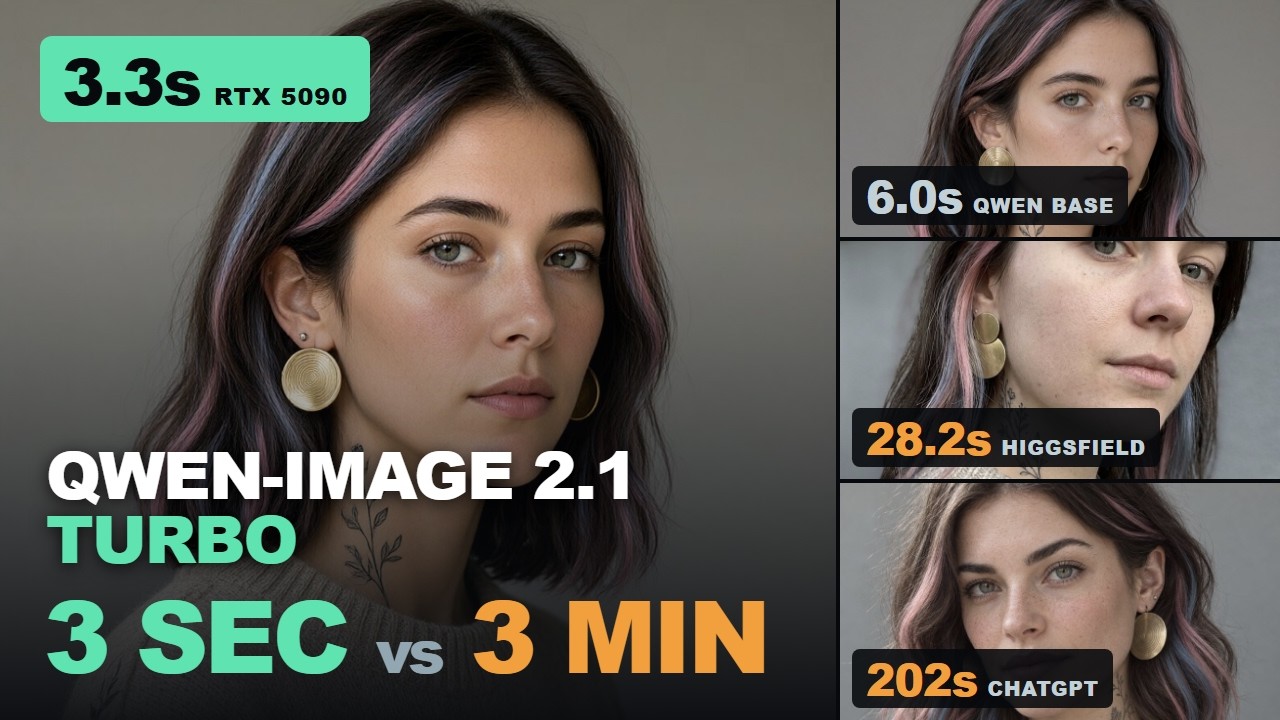
Qwen-Image 2.1 Turbo, run locally
Qwen's 8-step version of Qwen-Image 2.1, next to the regular model on the same prompts. Each test shows both images, the prompt and the time on my RTX 3060.
23 prompts, Qwen-Image 2.1 Turbo and Qwen-Image 2.1
9 October 2026
LTX 2.5 Creative Lab LoRAs, tested locally
Lightricks has released a set of official LoRAs for LTX 2.5 that add things the base model does not do on its own, from building a shot out of a reference sheet to colouring a black-and-white film. I ran 14 of them in ComfyUI on my own desktop, plus three tests that chain two LoRAs in one generation.
31 prompts, LTX 2.5
3 October 2026
Higgsfield effects vs MiniMax H3
Eleven Higgsfield effects and motion presets, remade locally with MiniMax H3 Ref2VA in ComfyUI from the same character photo. Each round has the H3 prompt, the photo and a frame from both sides.
11 prompts, Higgsfield and MiniMax H3
23 September 2026
Qwen-Image 2.1, run locally
Qwen-Image 2.1 generates and edits with one 7 billion parameter model, and its autoencoder carries an alpha channel, so transparency comes out of the model rather than a background remover. Everything below ran locally on an RTX 3060, with every prompt exact and every timing measured.
26 prompts, Qwen-Image 2.1
20 September 2026
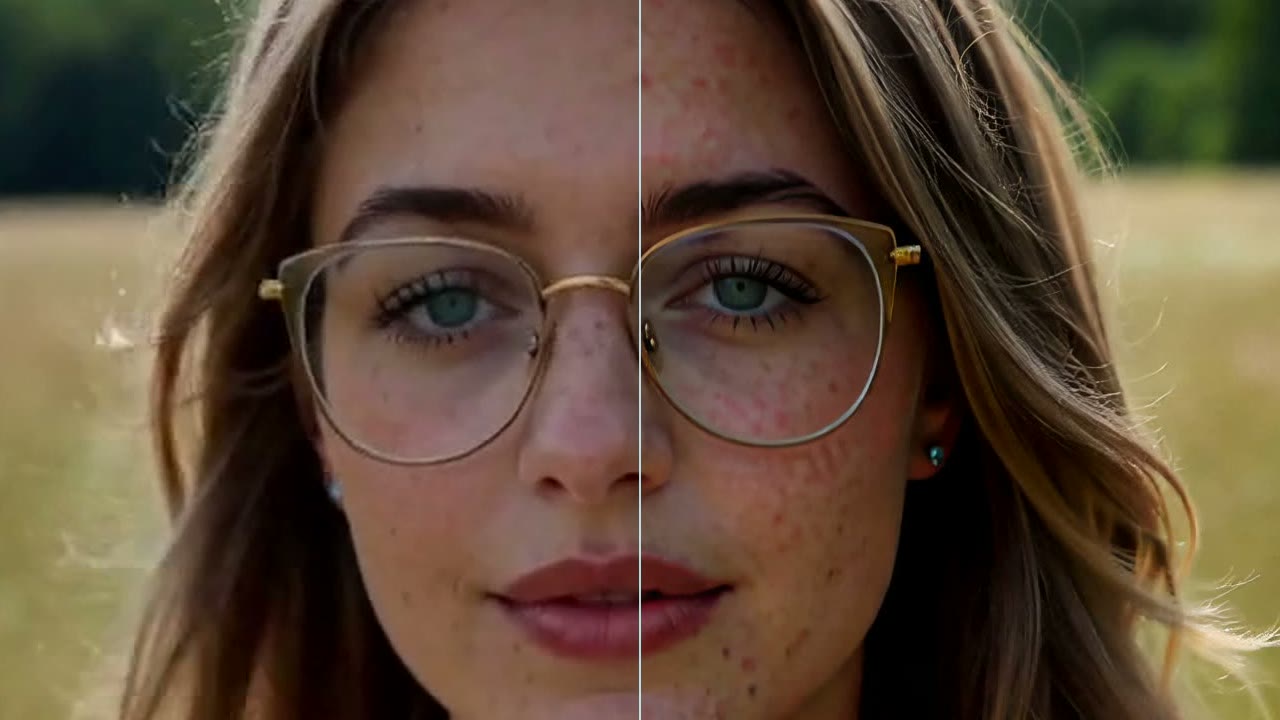
Video upscaling methods compared
Eleven upscalers on the same five clips, every output at exactly 2x.
11 methods on 5 clips, with every workflow and measurement
5 September 2026
MiniMax H3 long takes from chained renders
MiniMax H3 renders top out at about fifteen seconds. To get past that, every render opens on an exact replay of the last 39 frames of the render before it, so the join is the same frames rather than similar frames. Character, street and voice all stay put across it.
27 prompts, MiniMax H3
29 August 2026
First Date, a short film with MiniMax H3
A one minute short film made with ComfyUI's stock MiniMax H3 reference-to-video template, with two characters who stay the same person from shot to shot, in the same restaurant, with the same voice.
27 prompts, MiniMax H3
21 August 2026
MiniMax H3 vs LTX 2.5
MiniMax H3 and LTX 2.5 are both open-weight image to video models, and both generate their own speech and audio in the same pass. They ran head to head on one desktop, nine rounds each, with a winner called on every one.
10 prompts, MiniMax H3 and LTX 2.5
15 August 2026
MiniMax H3 with the Turbo LoRA
The Turbo LoRA setup for MiniMax H3: six steps instead of twenty plus, on a low VRAM card, entirely local in ComfyUI. The prompt carries a separate audio line, so the character says something and the model generates the speech along with the motion, from one still image.
1 prompt, MiniMax H3