 Loop Forge
2048 pixels in one pass: the canyon
From MOSS-Image add-ons, tested locally
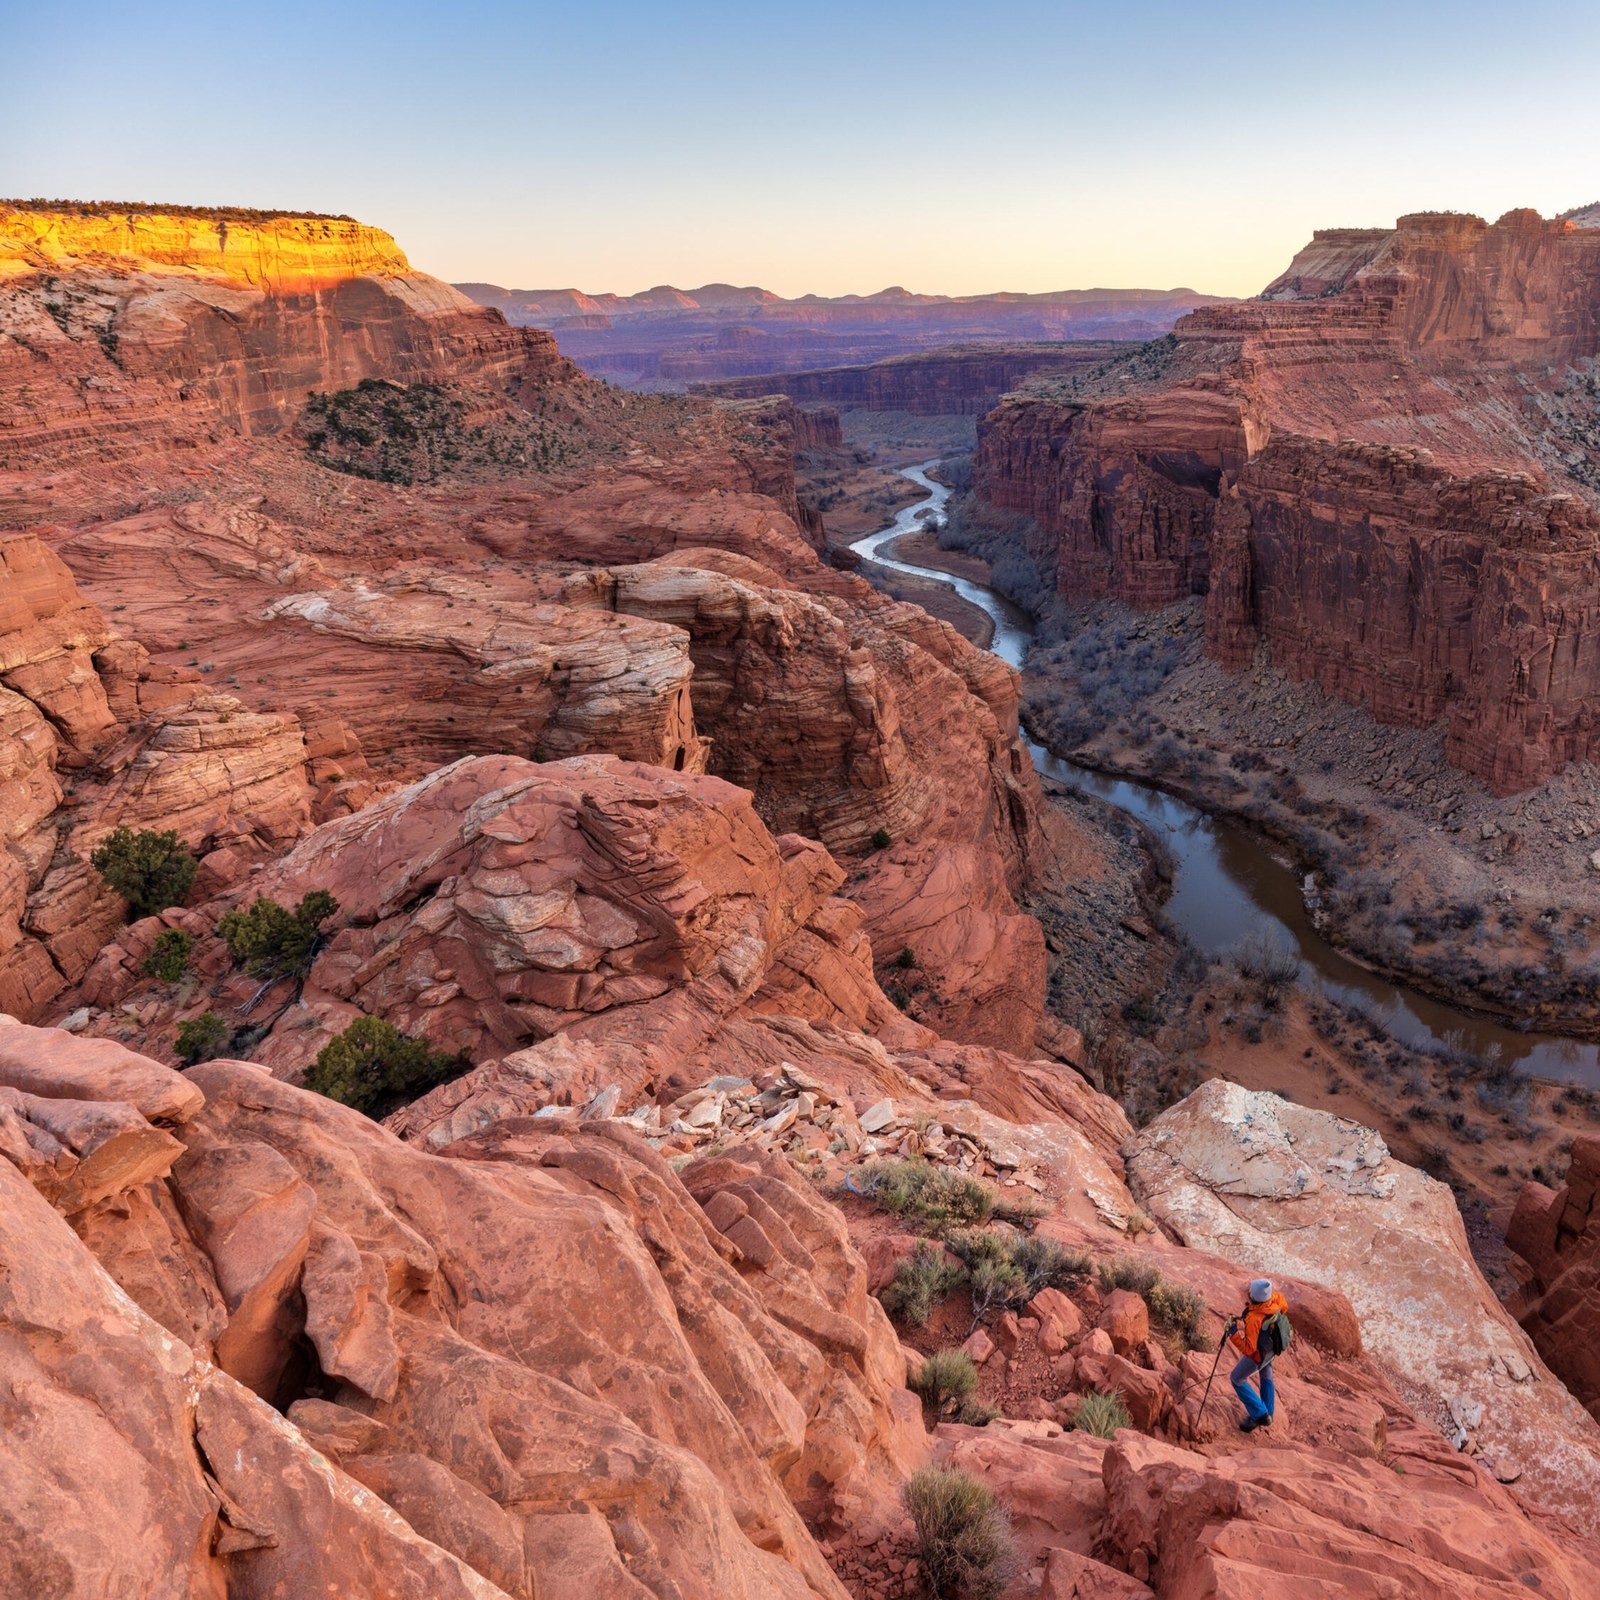
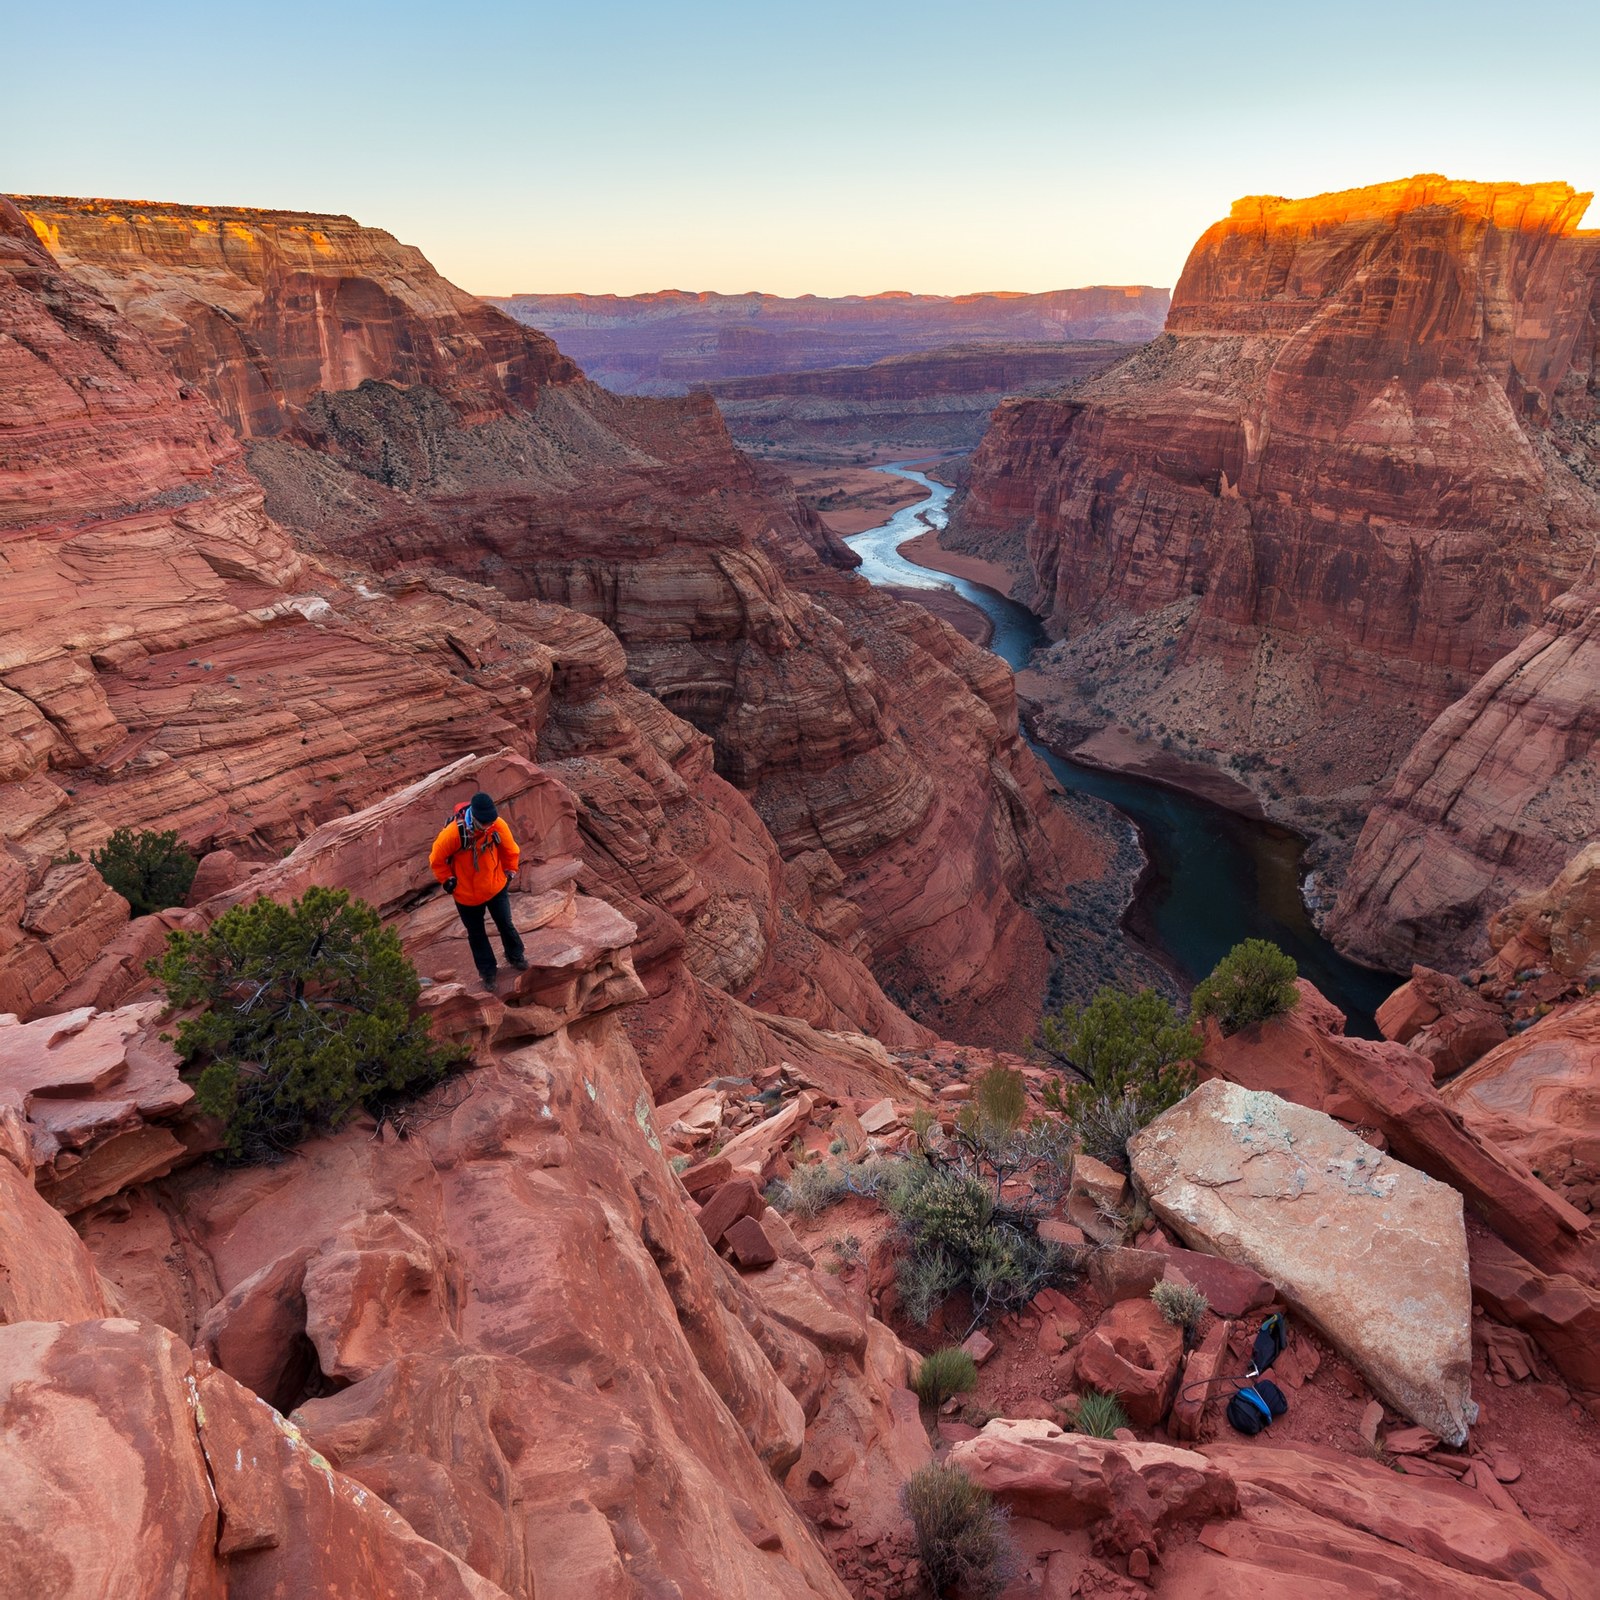
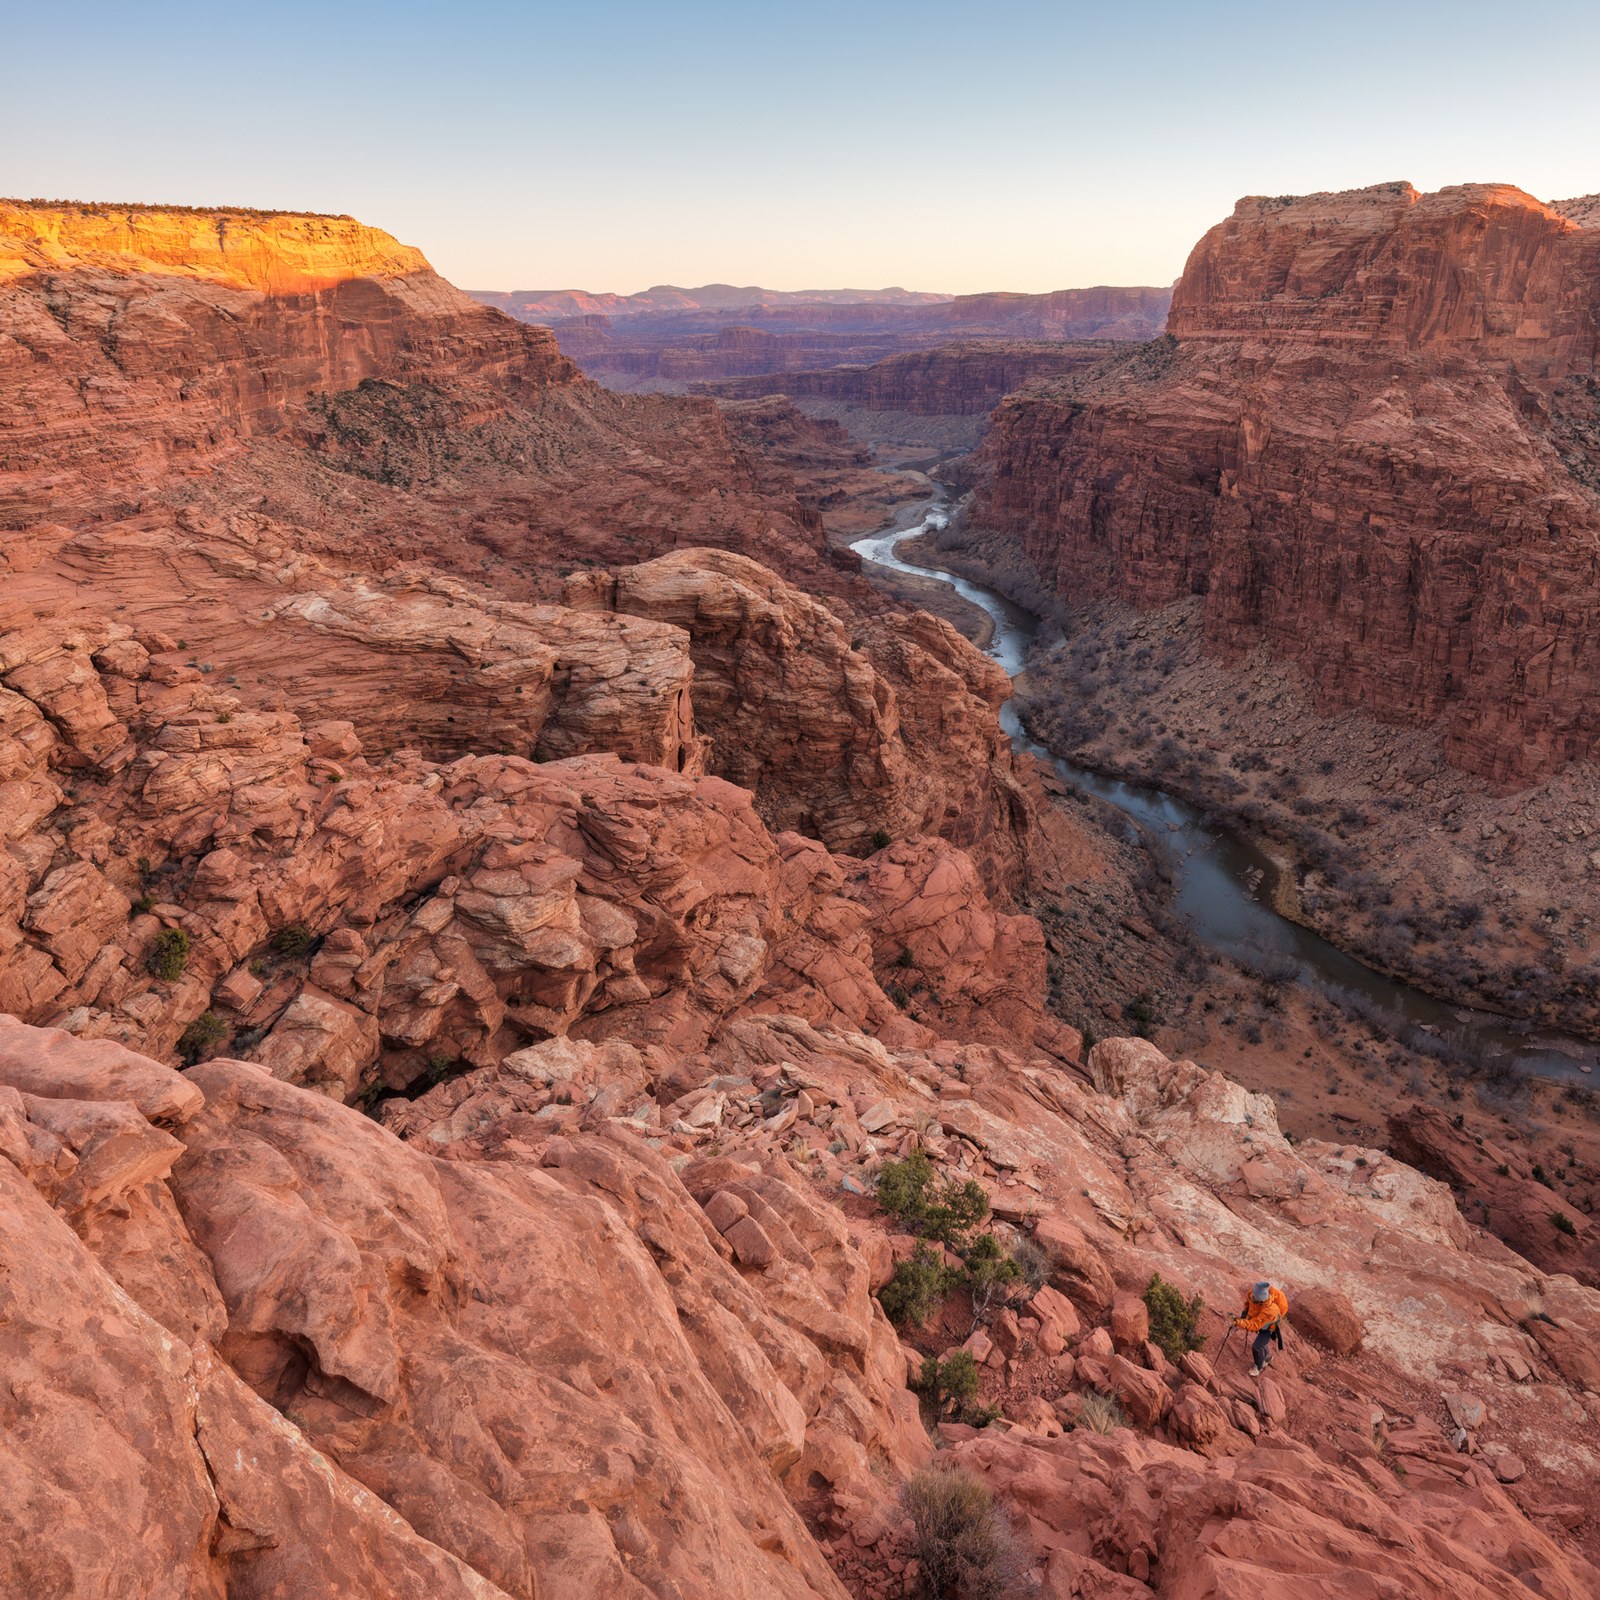
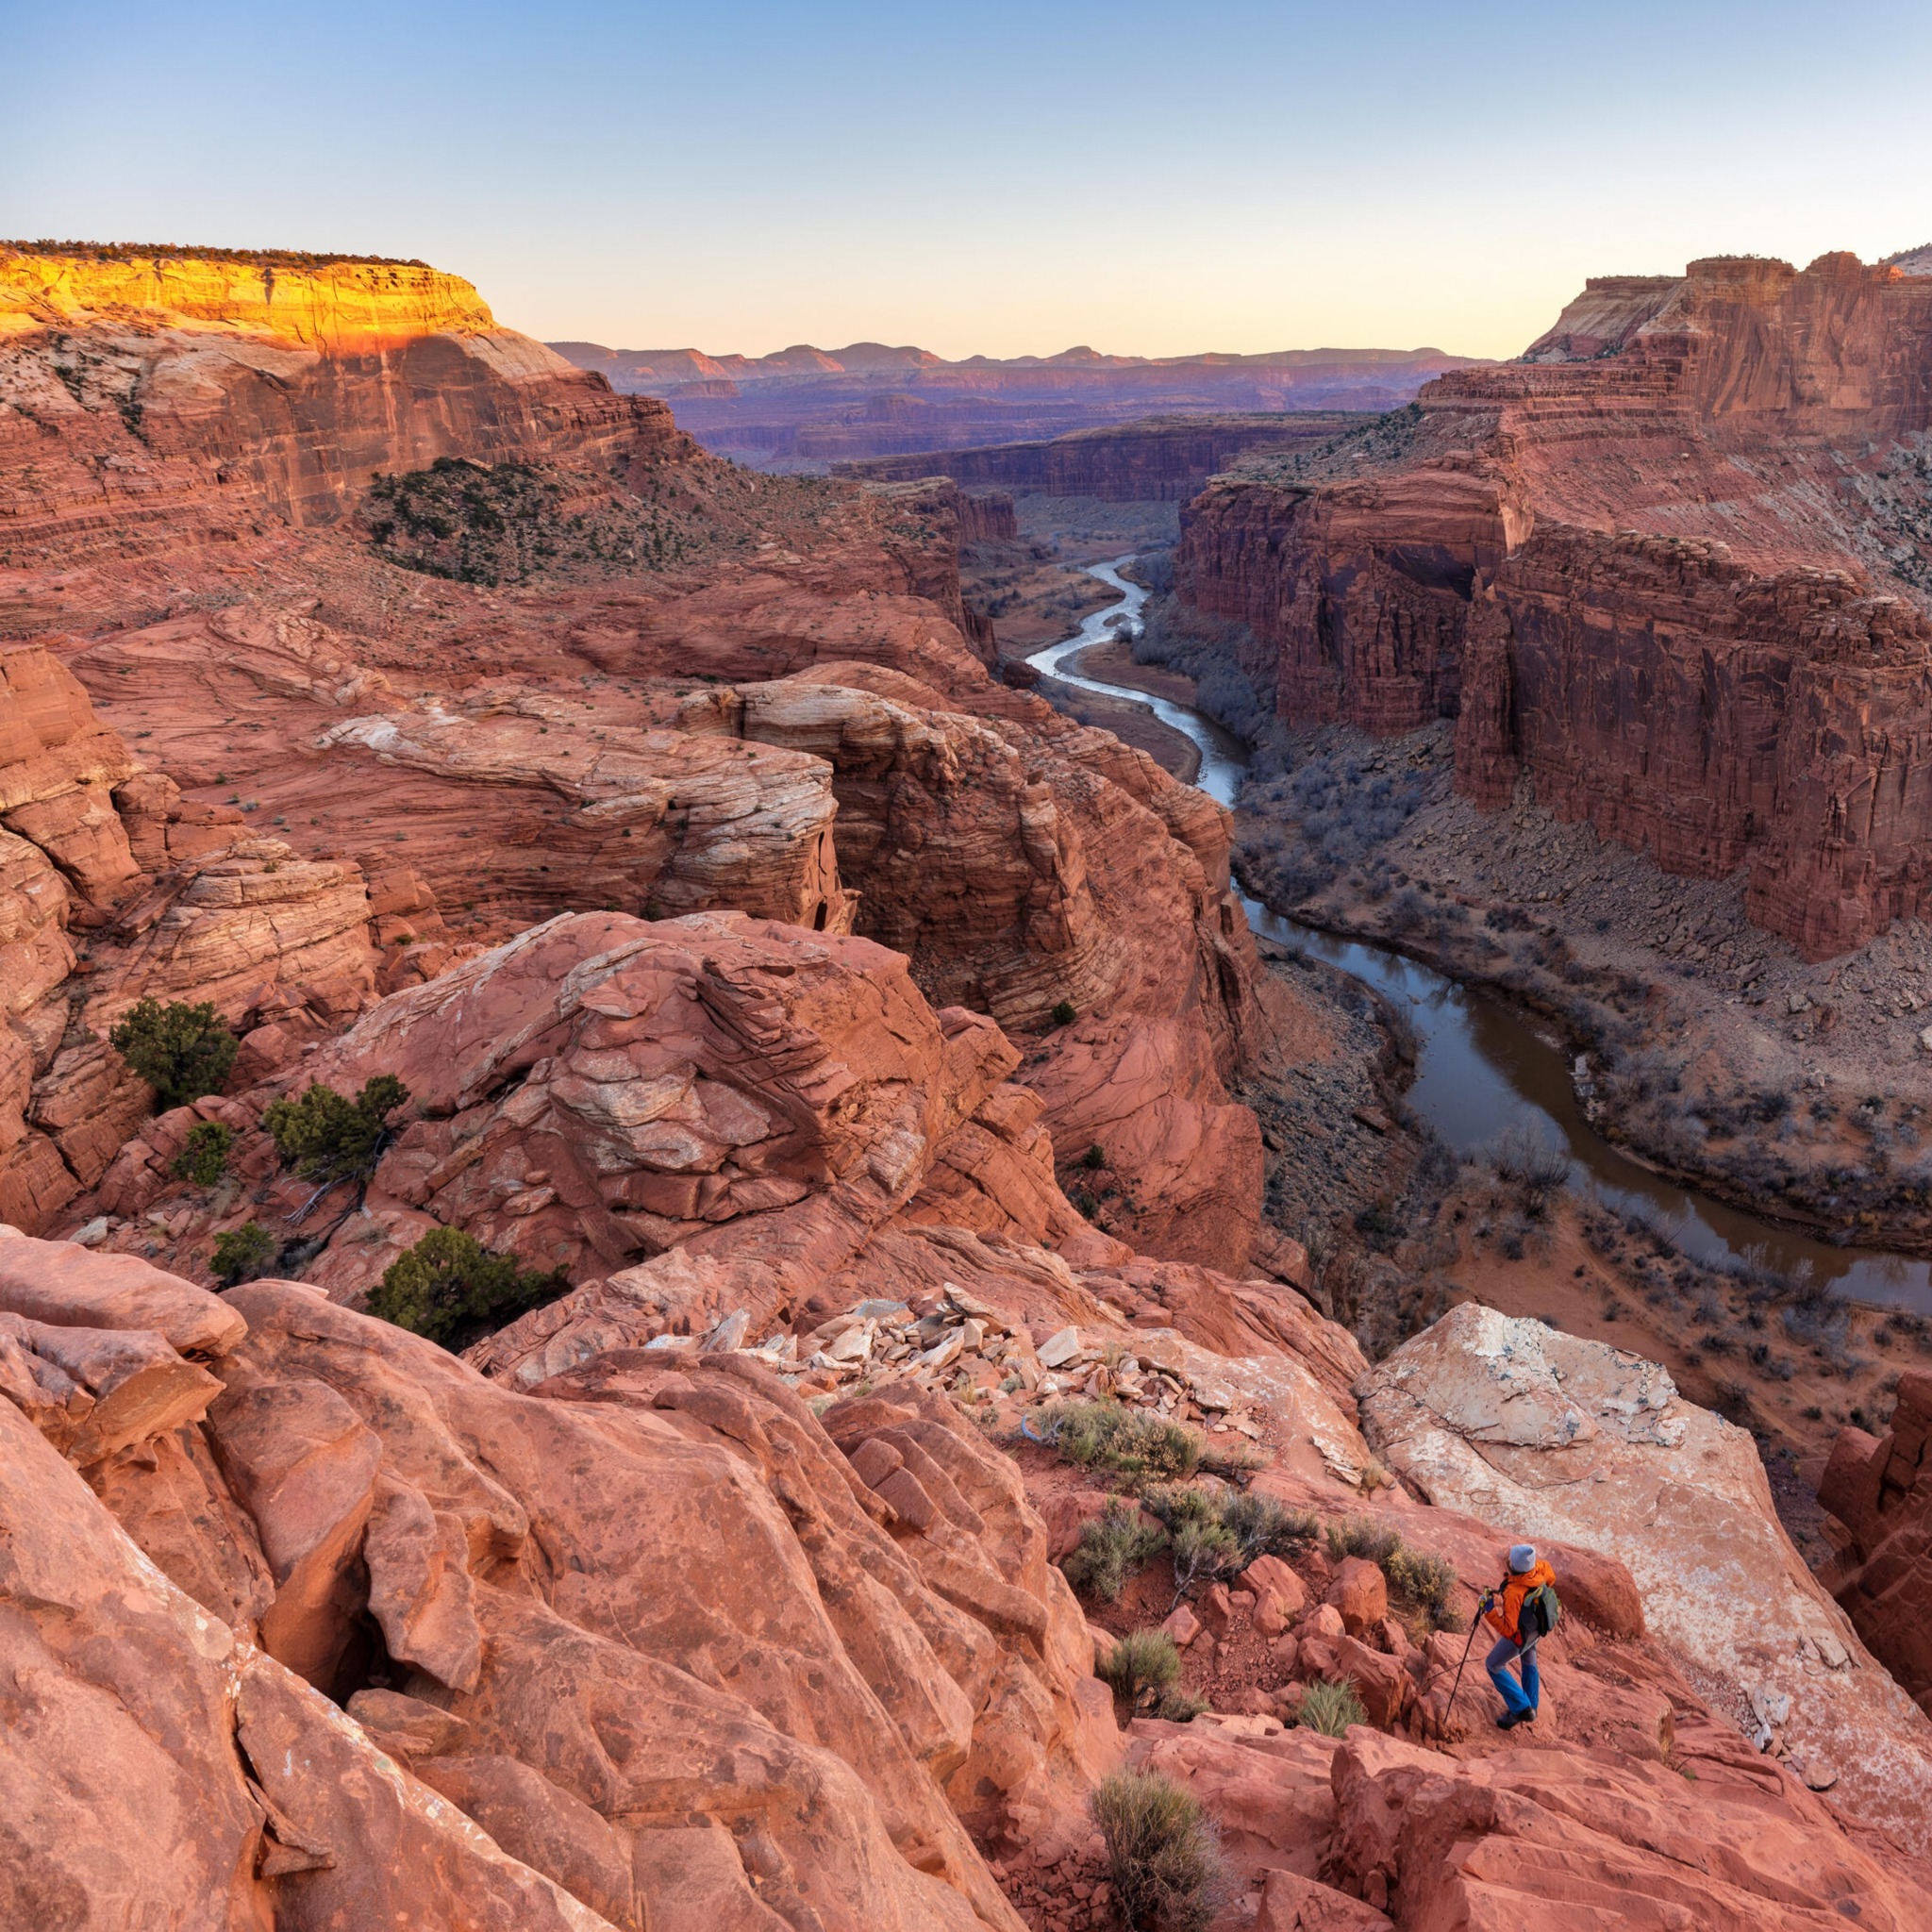
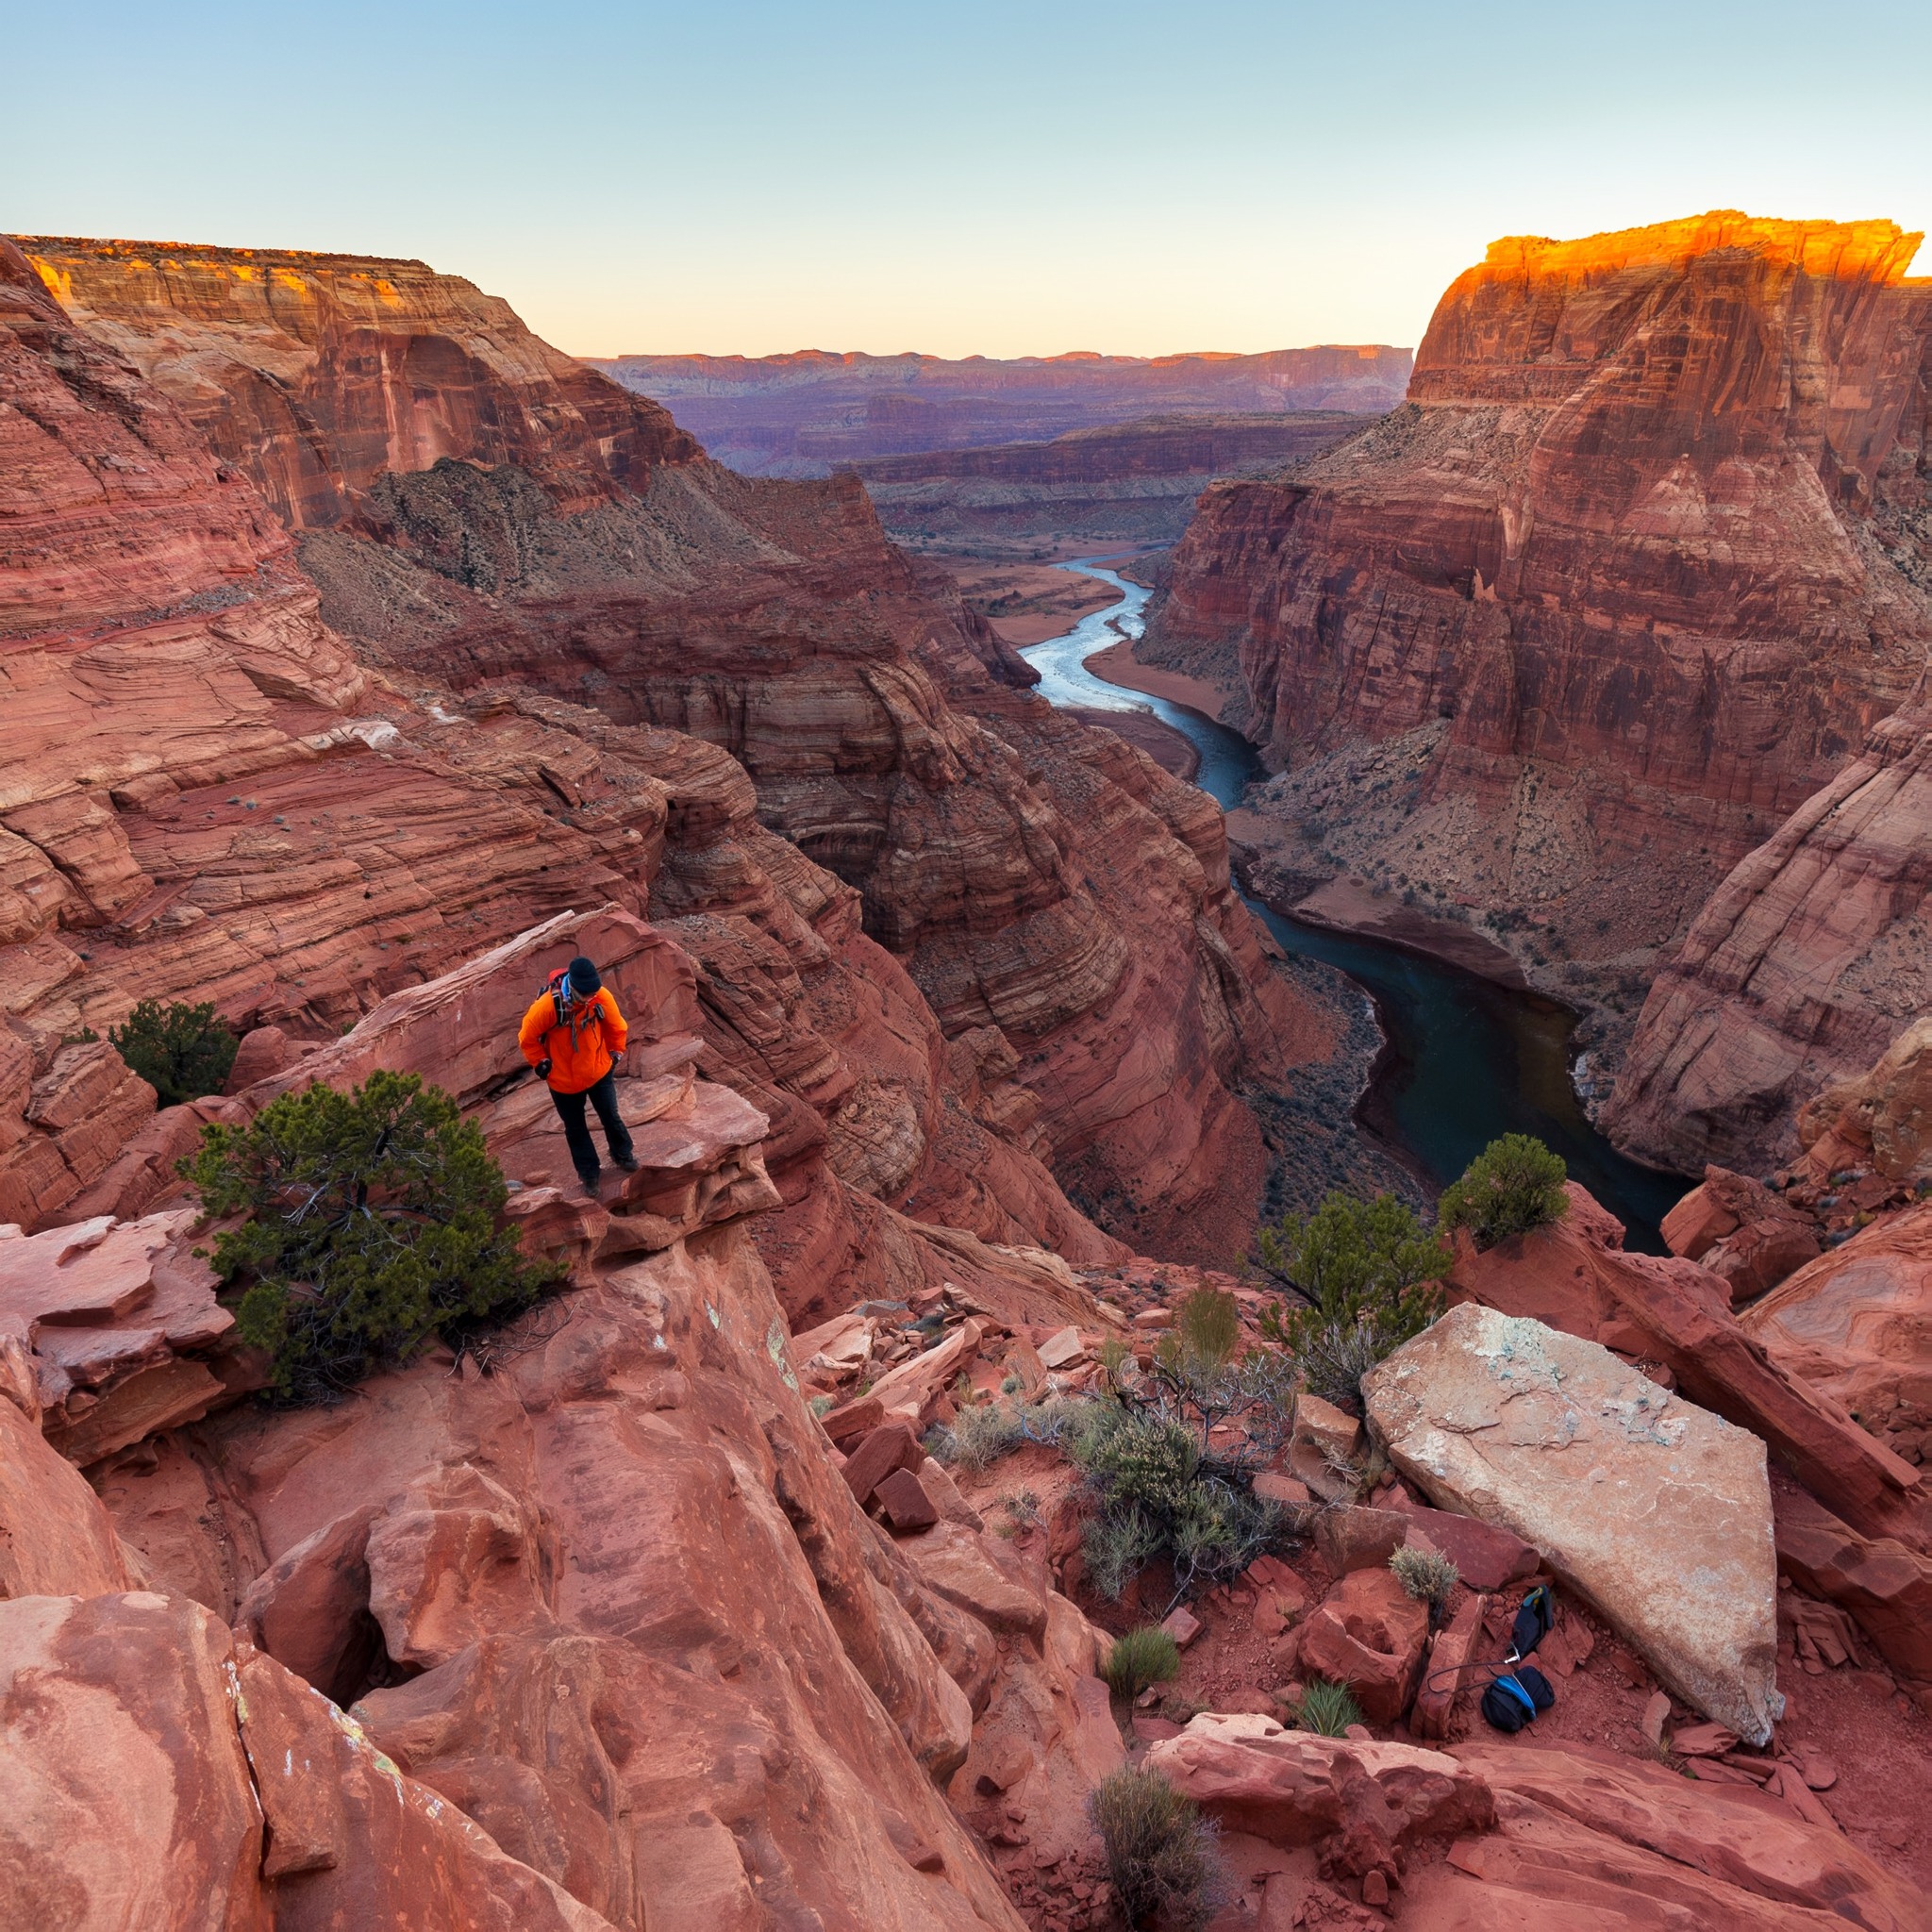
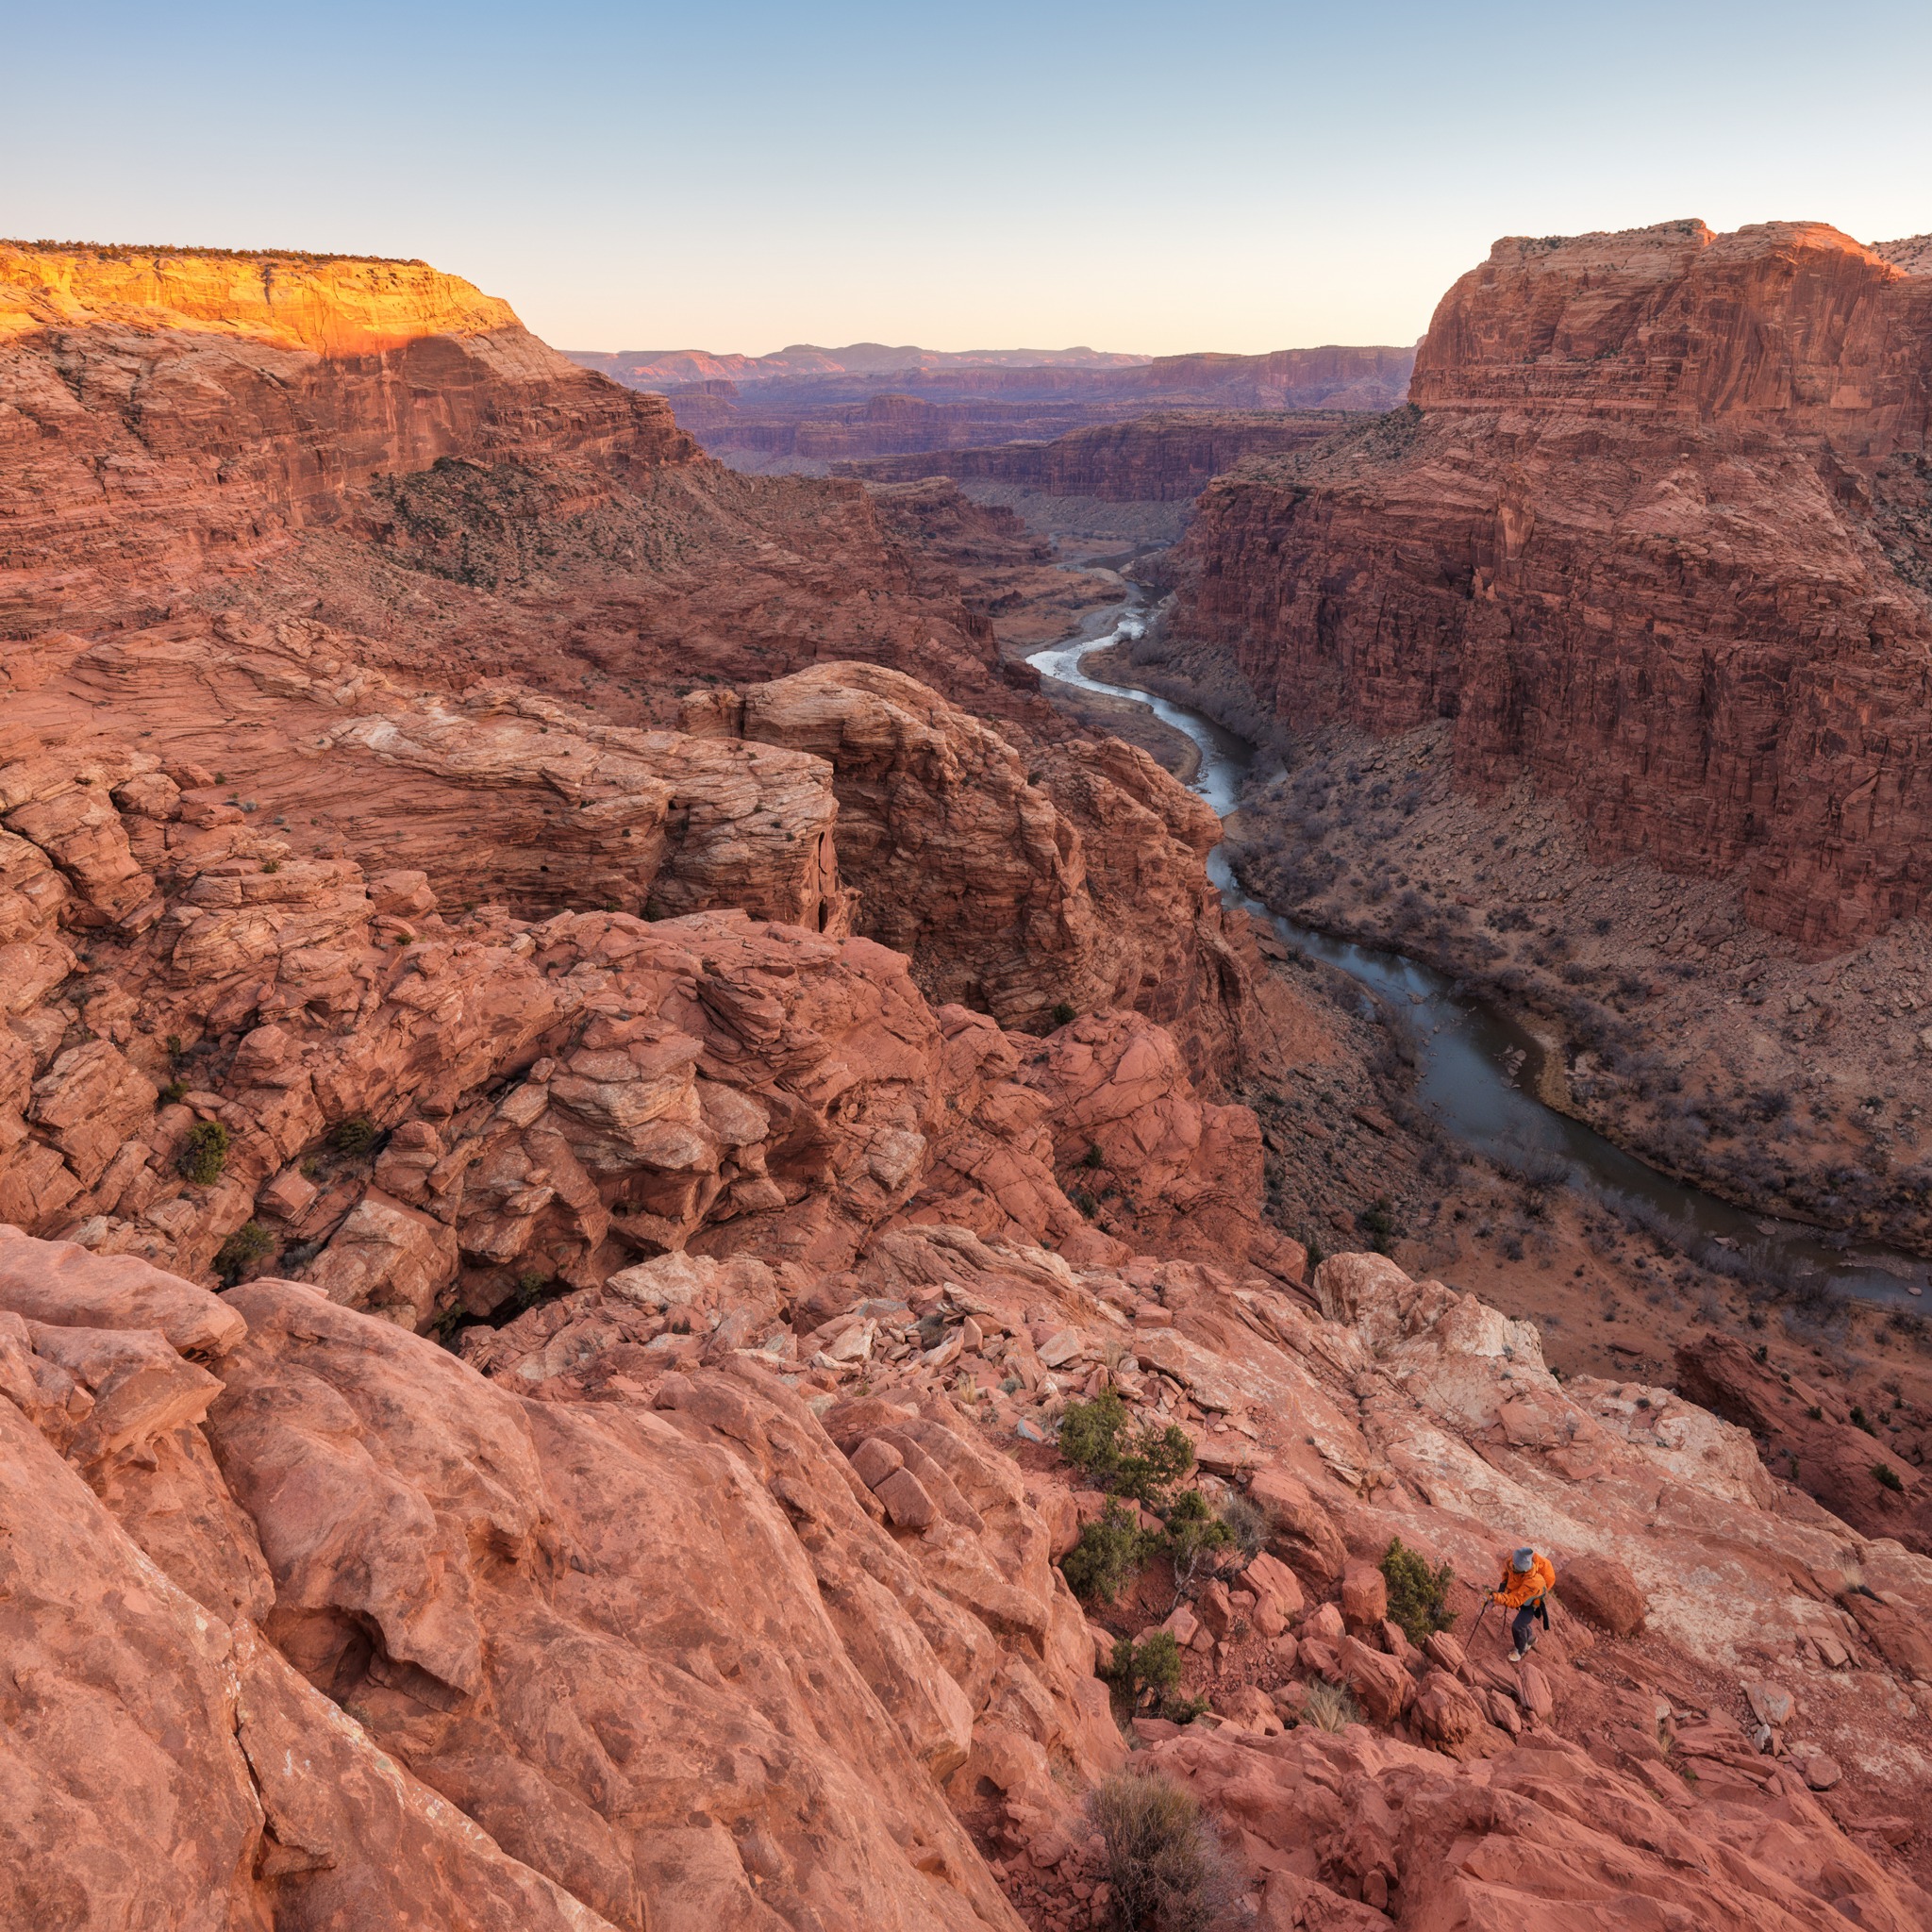
- Model
- MOSS-Image Base (moss_image_base_int8_convrot.safetensors)
- Output
- 2048×2048
- Sampling
- 25 steps, CFG 2.5, er_sde / simple
- Seed
- 101
- 2048 plain
- 235.5 s, peak VRAM 10.5 GiB
- Hi-res LoHa
- 238.2 s, peak VRAM 10.6 GiB
- Scale ROPE
- 239.7 s, peak VRAM 10.5 GiB
- Ran on
- RTX 3060, 12GB (local)
Both run on a 12 GB card, but it is a long wait for one image. They held together at that size, so if you need a really big picture, either one is worth the wait.
Ultra-detailed wide photograph of a desert canyon at sunrise: layered red sandstone walls, a winding river far below, a lone hiker in an orange jacket on a ledge in the foreground, tiny juniper trees, scattered rocks, distant mesas under a clear sky.
nsfw, worst quality, bad anatomy, watermark, jpeg artifact
Notes
The official Base template at 4 megapixels (2048×2048). The LoHa is comfyanonymous's hi-res test LoRA v0.5 at 1.0, for Base. Scale ROPE is a native ComfyUI node, set to 0.5 × 0.5 (NTK scaling from 1024 to 2048). 2048 plain has neither.
comfyanonymous/MOSS_image_MAX_ULTRA_hires_lora_test on Hugging Face (v0.5)
Comfy-Org workflow templates (the MOSS-Image templates ship with ComfyUI)
Run it yourself
This test loads no input files. Put the models below in place and drag the workflow onto ComfyUI.
| File | Put it in | Size |
|---|---|---|
| moss_image_base_int8_convrot.safetensors | models/diffusion_models | 5.4 GB |
| qwen3.5_9b_w4a8_gptq.safetensors | models/text_encoders | 7.3 GB |
| flux2-vae_small.safetensors | models/vae | 249.5 MB |
| moss_hires_lora_test_v0.5.safetensors | models/loras | 182.2 MB |
No custom nodes. Every node is part of ComfyUI 0.43.1 (frontend 1.57.6, templates 0.11.100).