 Loop Forge
Crash zoom in, fixed
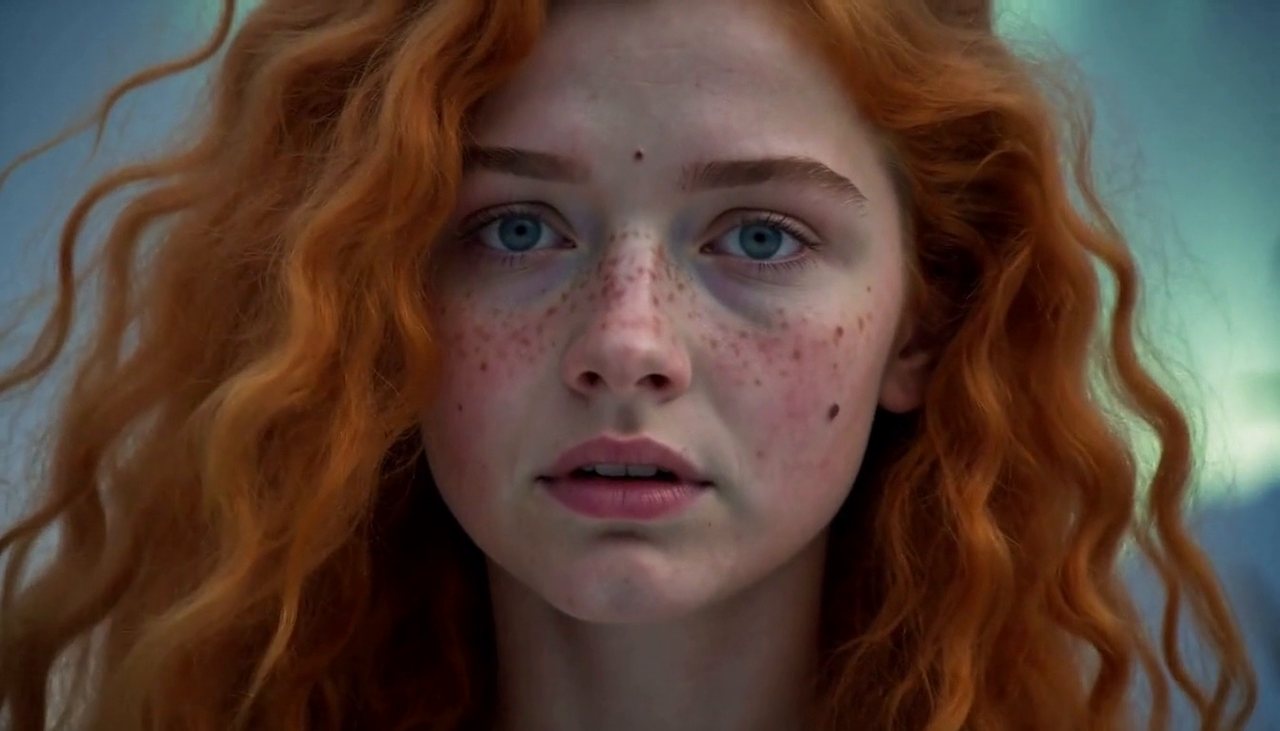
- Resolution
- 1344×768
- Length
- 124 frames, 5.17s
- Steps
- 20, res_multistep / simple, turbo LoRA off
- Seed
- 7
- Ran on
- RTX 3060, 12GB (local)
What was wired in
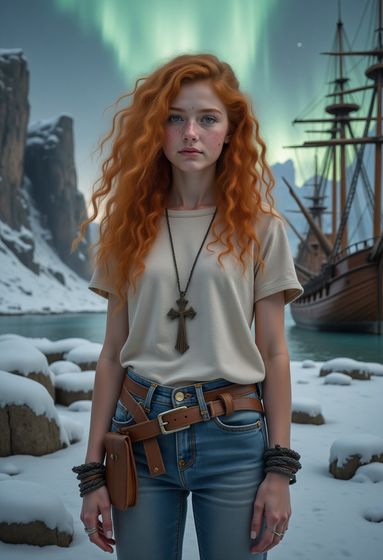 <Picture 1>
AmberCharacter reference plate
Camera clause
subject_definitions:
<Subject 1> is the person in <Picture 1>.

summary:
[reference generation] The target video shows <Subject 1> standing still on a snow-covered arctic coastline, in a wide shot, as the camera performs a crash zoom in.

retention_analysis:
<Subject 1> (appears in [Shot 1]): fully_preserved - her face, identity and clothing are held identical to <Picture 1> in every frame with zero drift.

detailed_description:
The target video is live-action and cinematic.
[Shot 1] A wide shot places <Subject 1> small and complete in frame on the snowy rocky shore, standing in place on the snowy rocky shore, breathing softly, hair and clothing stirring in the air, blinking and shifting her weight a little as people naturally do, with dark rocky cliffs, patches of green aurora borealis in the sky, still water, and an old wooden sailing ship with tall masts behind her. The camera is locked off on a tripod and holds the wide shot completely still for the first two seconds; only the zoom lens changes and the camera body never moves. Between one frame and the next the lens crash zooms in to a tight close-up of her face: the whole change takes only two or three frames, as abrupt as a cut, with a streak of zoom blur on those few frames only, and nothing shifts against anything else, the background simply magnifies flat together with her. After it lands the close-up is locked and does not change. As the shot plays out, <Subject 1>'s expression shifts from blank and neutral into dawning realization and slight shock.

overall_soundscape: A faint cold wind continues throughout, with distant creaking from the ship's rigging

non_diegetic_music: A single sustained low string note swells partway through the shot, then fades toward the end
Notes
The prompt asks for the zoom to take about 200ms. H3 took about 2.6 seconds. The still and the video show the clip after snap.py, which finds the zoom and speeds it up to three frames. The prompt is kept exactly as it ran.
Run it yourself
Download everything for this test (.zip, 0.6 MB). It holds the workflow, every input it loads and a README. Copy the inputs into ComfyUI/input, put the models below in place and drag the workflow onto ComfyUI.
| File | Put it in | Size |
|---|---|---|
| minimax_h3_ref2va_pruned_int8_convrot.safetensors | models/diffusion_models | 21.0 GB |
| qwen3vl_32b_minimax_h3_nvfp4_awq.safetensors | models/text_encoders | 15.7 GB |
| minimax_h3_video_vae_fp16.safetensors | models/vae | 5.2 GB |
| minimax_h3_audio_vae_fp32.safetensors | models/vae | 605.3 MB |
No custom nodes. Every node is part of ComfyUI 0.41.0.