 Loop Forge
Slow pan reveal
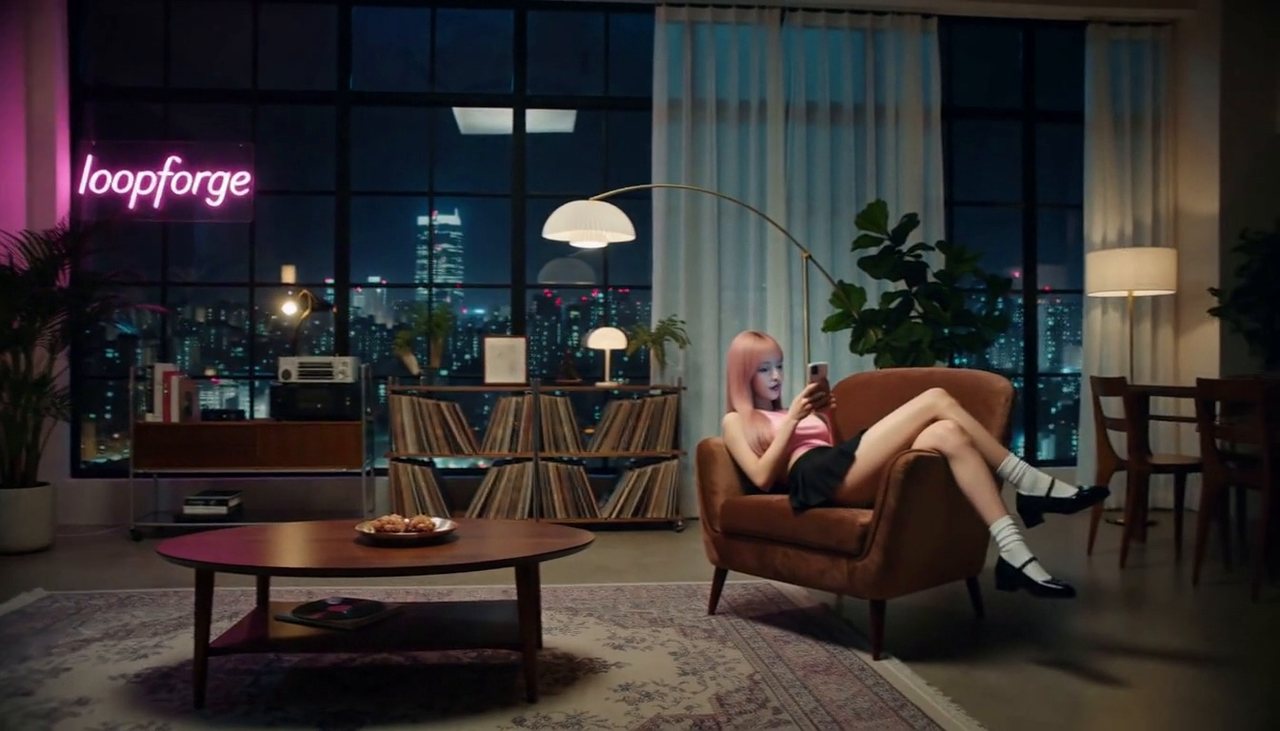
- Resolution
- 1344×768
- Length
- 124 frames, 5.17s
- Steps
- 20, res_multistep / simple, turbo LoRA off
- Seed
- 7
- Ran on
- RTX 3060, 12GB (local)
What was wired in
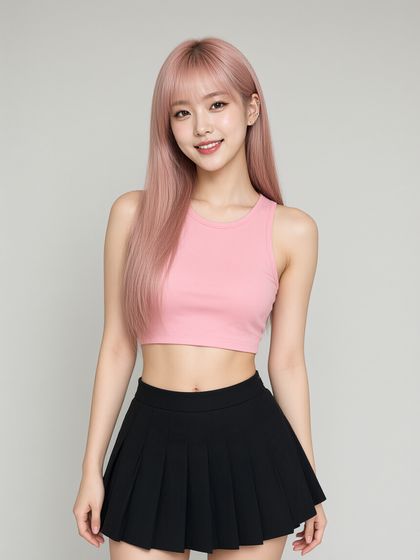 <Picture 1>
JinCharacter reference plate
Camera clause
subject_definitions:
<Subject 1> is the person in <Picture 1>, with long sleek straight pastel-pink hair with a soft fringe, small silver ear cuffs, a fitted pink cropped tank top and a pleated black mini skirt.

summary:
[reference generation] The target video shows <Subject 1> lying sideways across a velvet armchair in a stylish loft apartment at night, in a wide shot of the place, as the camera performs a slow pan reveal.

retention_analysis:
<Subject 1> (appears in [Shot 1]): fully_preserved - her face, identity and clothing (long sleek straight pastel-pink hair with a soft fringe, small silver ear cuffs, a fitted pink cropped tank top and a pleated black mini skirt) are held identical to <Picture 1> in every frame with zero drift.

detailed_description:
The target video is live-action and cinematic.
[Shot 1] A wide shot looks across floor-to-ceiling windows over the city lights, shelves of vinyl records, a pink neon sign on the wall that reads "loopforge" in lowercase letters, and tall potted plants in the living room, with no one in view. The camera stays in one place and pans right at slow speed across the place, and comes to rest on <Subject 1> lying sideways across a wide velvet armchair at the right, her back propped against one arm of the armchair and her legs draped over the other arm, her lower legs hanging in the air off the side of the armchair and not resting on anything, scrolling on her phone, framing her in a medium shot as the screen lights her face.

overall_soundscape: The quiet hum of the city outside and the soft tap of a thumb on a phone screen

non_diegetic_music: A single sustained low string note swells partway through the shot, then fades toward the end
Run it yourself
Download everything for this test (.zip, 1.2 MB). It holds the workflow, every input it loads and a README. Copy the inputs into ComfyUI/input, put the models below in place and drag the workflow onto ComfyUI.
| File | Put it in | Size |
|---|---|---|
| minimax_h3_ref2va_pruned_int8_convrot.safetensors | models/diffusion_models | 21.0 GB |
| qwen3vl_32b_minimax_h3_nvfp4_awq.safetensors | models/text_encoders | 15.7 GB |
| minimax_h3_video_vae_fp16.safetensors | models/vae | 5.2 GB |
| minimax_h3_audio_vae_fp32.safetensors | models/vae | 605.3 MB |
No custom nodes. Every node is part of ComfyUI 0.41.0.