 Loop Forge
Rack focus
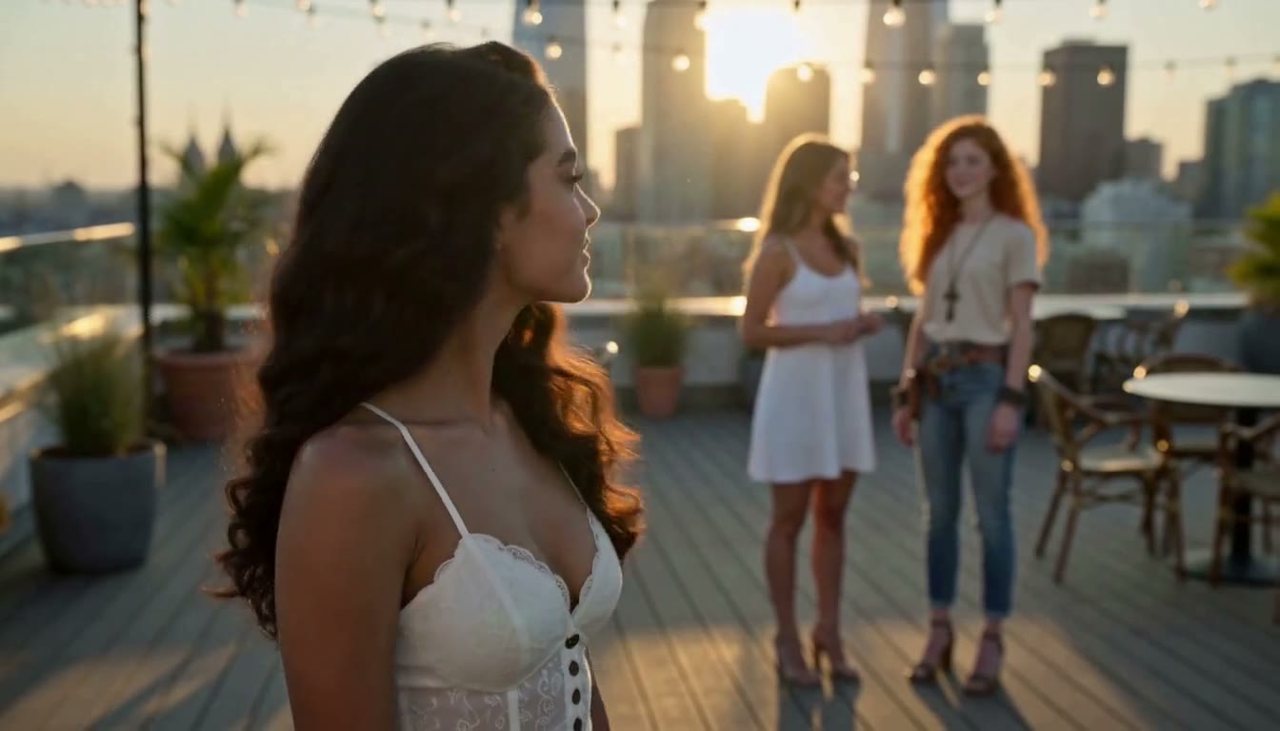
Watch it in the video at 3:30
- Resolution
- 1344×768
- Length
- 124 frames, 5.17s
- Steps
- 20, res_multistep / simple, turbo LoRA off
- Seed
- 552013742
- Ran on
- RTX 5090 on RunPod
Rent the same kind of GPU on RunPodAffiliate link: Loop Forge gets credit if you sign up through it, at no extra cost to you.
What was wired in
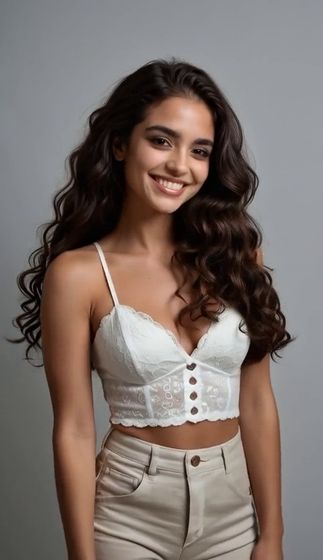 <Picture 1>
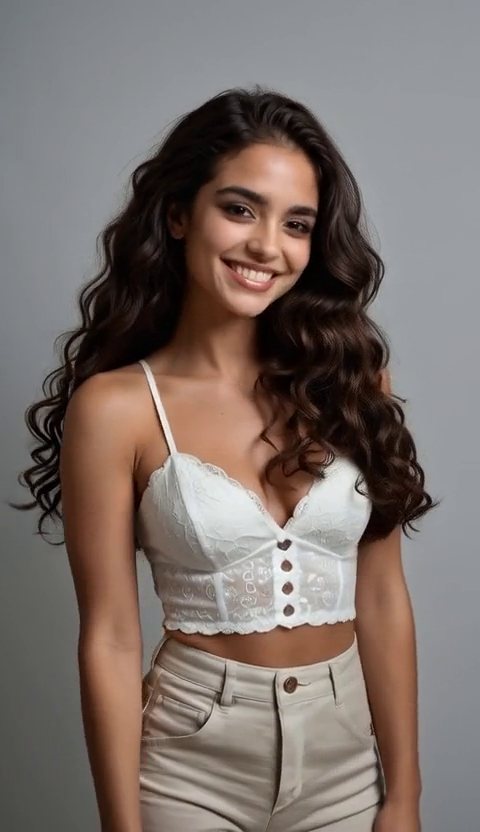
SofiaCharacter reference plate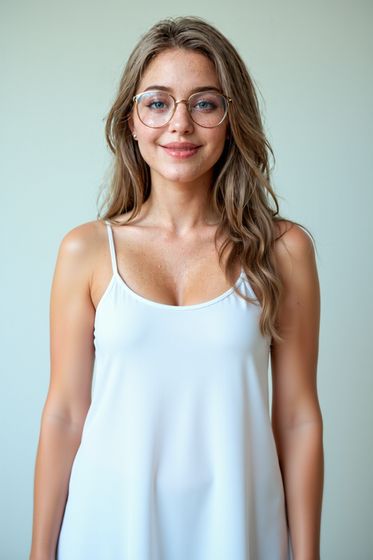 <Picture 2>
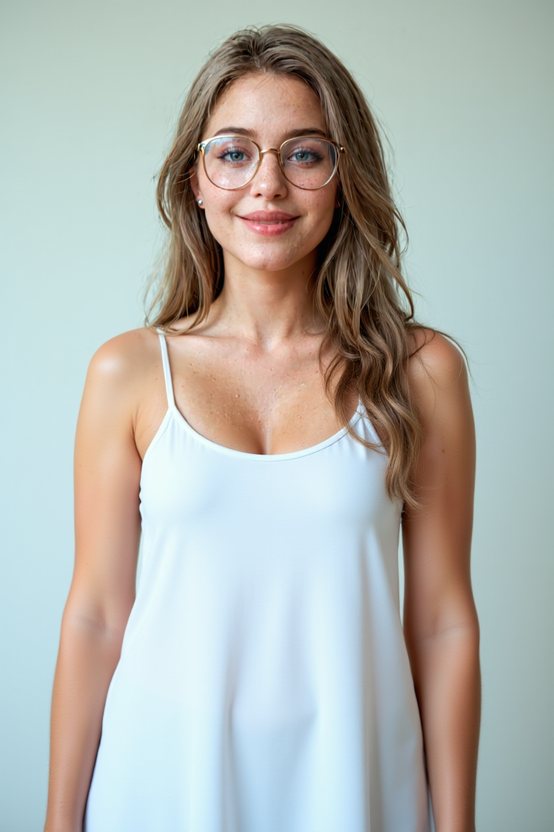
AllieCharacter reference plate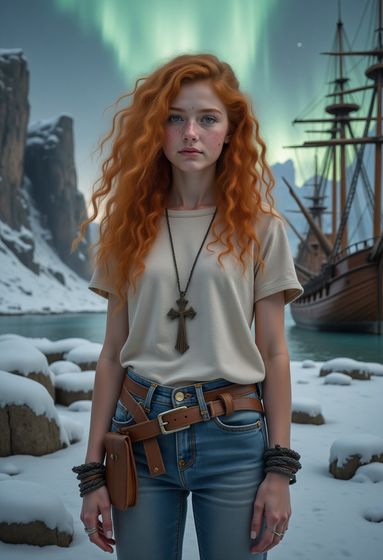 <Picture 3>
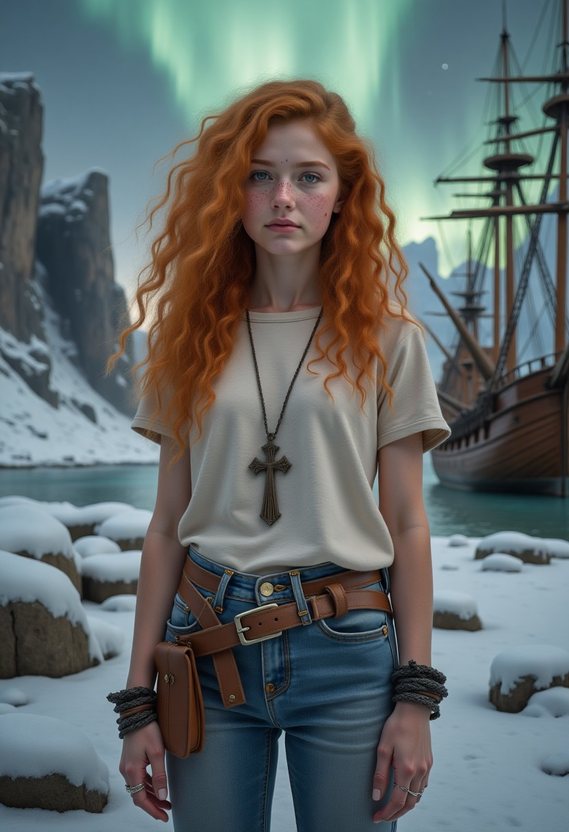
AmberCharacter reference plate
Camera and lensCamera clause
subject_definitions:
<Subject 1> is the young woman in <Picture 1>: long dark brown wavy hair, warm olive skin and a bright open smile, wearing a white lace-trimmed cropped camisole and high-waisted beige trousers. Her exact facial structure, features and proportions stay identical to <Picture 1> in every frame.
<Subject 2> is the second young woman in <Picture 2>: long light brown wavy hair, fair freckled skin, round gold-rimmed glasses, wearing a simple white slip dress with thin straps. Her exact facial structure, features and proportions stay identical to <Picture 2> in every frame.
<Subject 3> is the third young woman in <Picture 3>: long wavy ginger-red hair, fair skin with light freckles, wearing a cream short-sleeve t-shirt, a dark cord necklace with a metal cross pendant, high-waisted blue jeans with a brown leather belt and a small brown pouch, and woven cord wrist wraps on both wrists. Her exact facial structure, features and proportions stay identical to <Picture 3> in every frame.

summary:
[reference generation] The target video shows <Subject 1> in the foreground with <Subject 2> and <Subject 3> talking together far behind her in a sunlit city rooftop terrace at golden hour, in a medium-wide shot, as the camera performs a rack focus.

retention_analysis:
<Subject 1> (appears in [Shot 1]): fully_preserved - her face, identity and clothing are held identical to <Picture 1> in every frame with zero drift.
<Subject 2> (appears in [Shot 1]): fully_preserved - her face, identity and clothing are held identical to <Picture 2> in every frame with zero drift.
<Subject 3> (appears in [Shot 1]): fully_preserved - her face, identity and clothing are held identical to <Picture 3> in every frame with zero drift.

detailed_description:
The target video is live-action and cinematic, shot on an ARRI Alexa with a Cooke S4 75mm prime wide open, locked off, focus pulled with a follow focus, warm golden-hour sunlight with strong lens flare, a rich saturated palette.
[Shot 1] A medium-wide shot holds two distinct depth planes at once: <Subject 1> close to camera and the rooftop opening out well behind her. She is standing in place on the warm rooftop deck, breathing softly, hair and clothing stirring in the air, blinking and shifting her weight a little as people naturally do, with low sun flaring between distant towers, potted plants and strings of lights behind her. The camera holds a static shot. <Subject 1> stands close to camera in sharp focus while <Subject 2> and <Subject 3> stand talking together far behind her, soft and unfocused. <Subject 1> slowly turns her head to look back at them, and the focus racks from her face to the two women - she falls into soft blur exactly as they resolve sharply. <Subject 1>'s idle curiosity sharpens into recognition as she turns, while <Subject 2> and <Subject 3> stay absorbed in their own conversation, laughing quietly together.

overall_soundscape: The two women's quiet conversation and laughter sits distant and indistinct behind the rooftop ambience, then lifts forward and becomes clearly audible as the focus reaches them.

non_diegetic_music: A faint sustained pad that shifts harmony once, at the moment the focus changes.